
Challenge
Summer heat throttled 70B runs in Frankfurt, costing a week per run.
Solution
A dedicated 2,048-GPU pod on its own fabric, racked in 11 days.
Result
19-day training runs, a third less energy, no thermal restarts.
Summer was the bottleneck
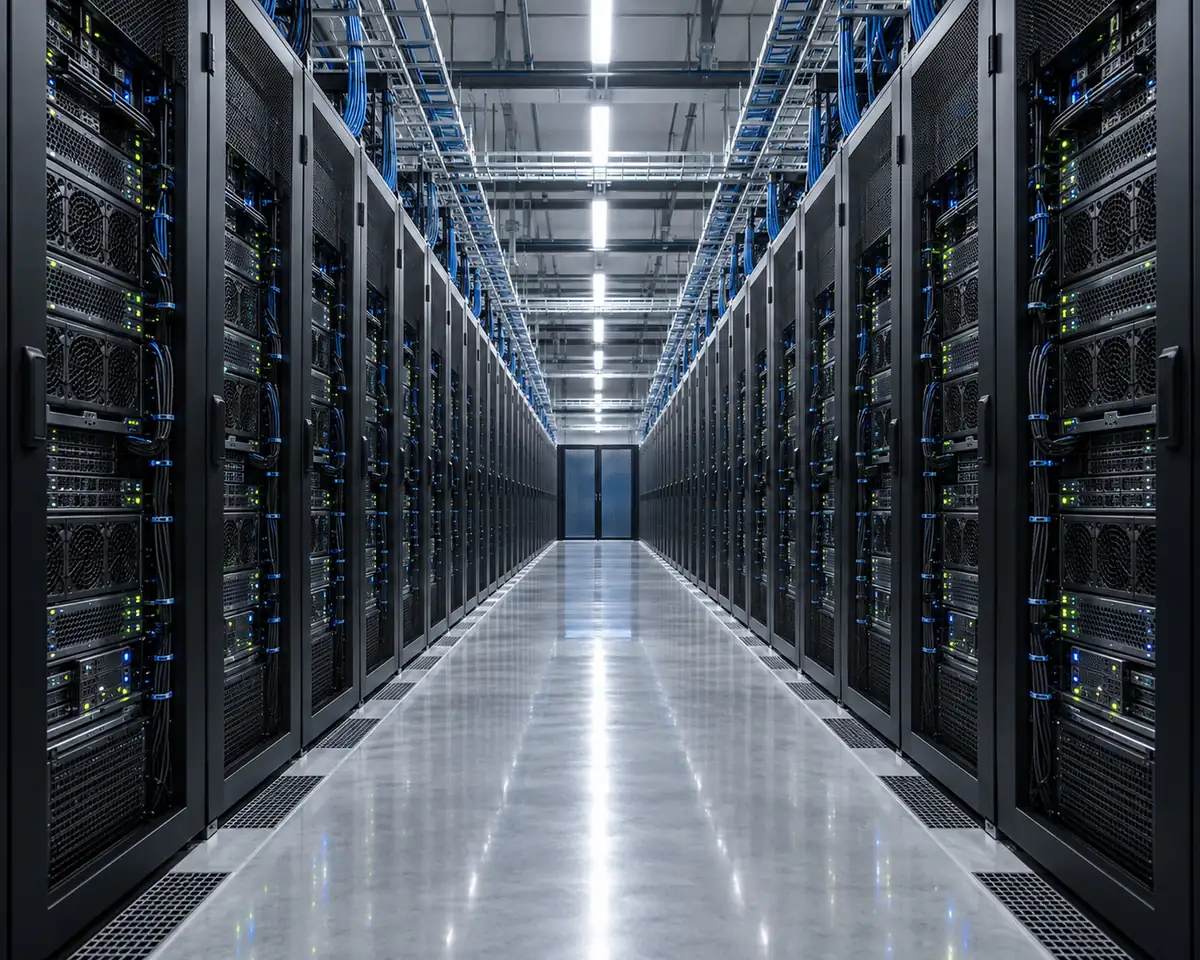
Tensorfield trains open-weight foundation models for European enterprises. In 2025 their 70B runs lived in a colocation hall outside Frankfurt, and every July the same thing happened: inlet temperatures climbed, GPUs throttled, and checkpoints were restored two or three times a week.
The team had tuned everything they could control. What they could not control was the air. A run planned for 19 days took 24, and the energy line on each run grew with it.
“We stopped planning around the weather. That alone gave us back a week per run.”
A pod of their own, in Hall A
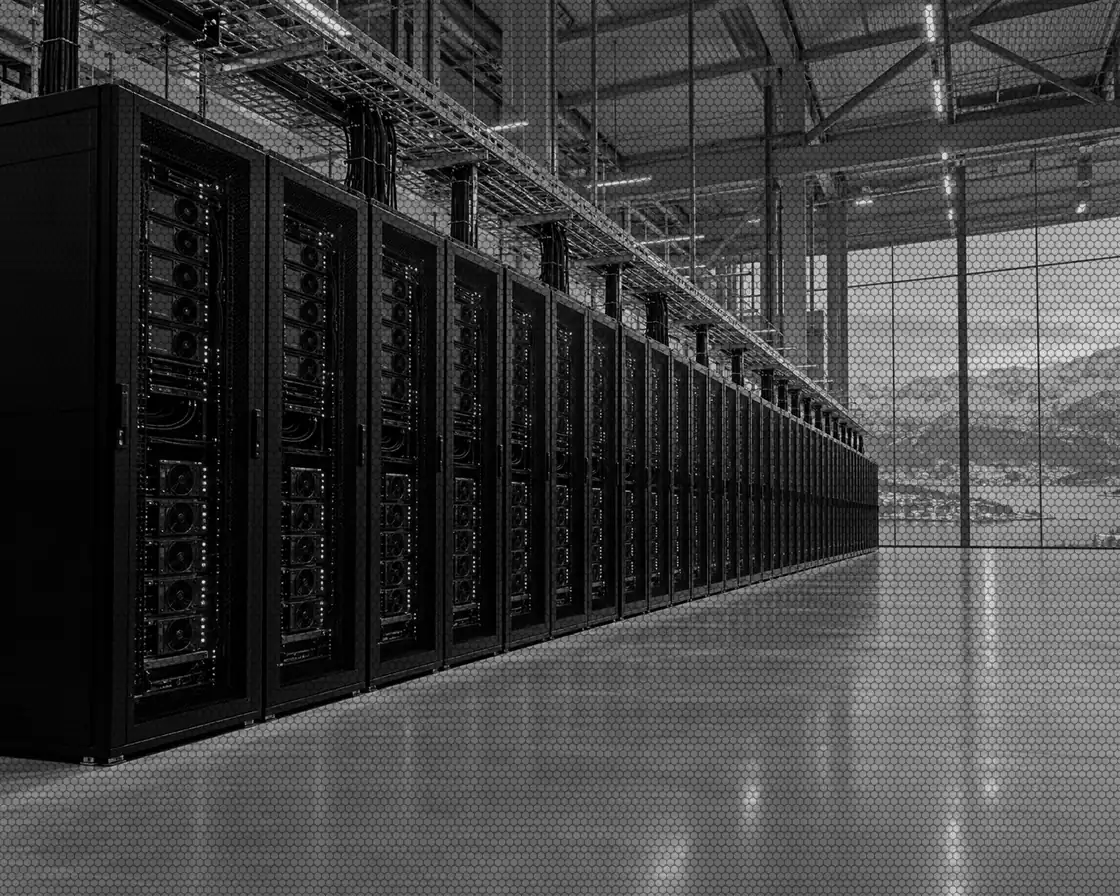
In January 2026 Tensorfield reserved a Dedicated pod of 2,048 H200s on N-01. The hall is cooled by outside air for all but a few days a year, and powered by hydro from the Narvik grid at a fixed rate for the full term.
What moved north
The full training stack on bare metal, with their own images and Slurm config.
2 PB of checkpoint storage, replicated inside the hall.
A dedicated 3.2 Tb/s InfiniBand fabric with no neighbours on the spine.
Six months in
The pod went live on 3 March 2026. Since then Tensorfield has trained two 70B models and one 140B ablation. Energy per run is down 34%, and job restarts are down 38%, almost all of them now caused by code rather than heat. The next run is booked on B300 capacity from Q1 2027.
